Introduction
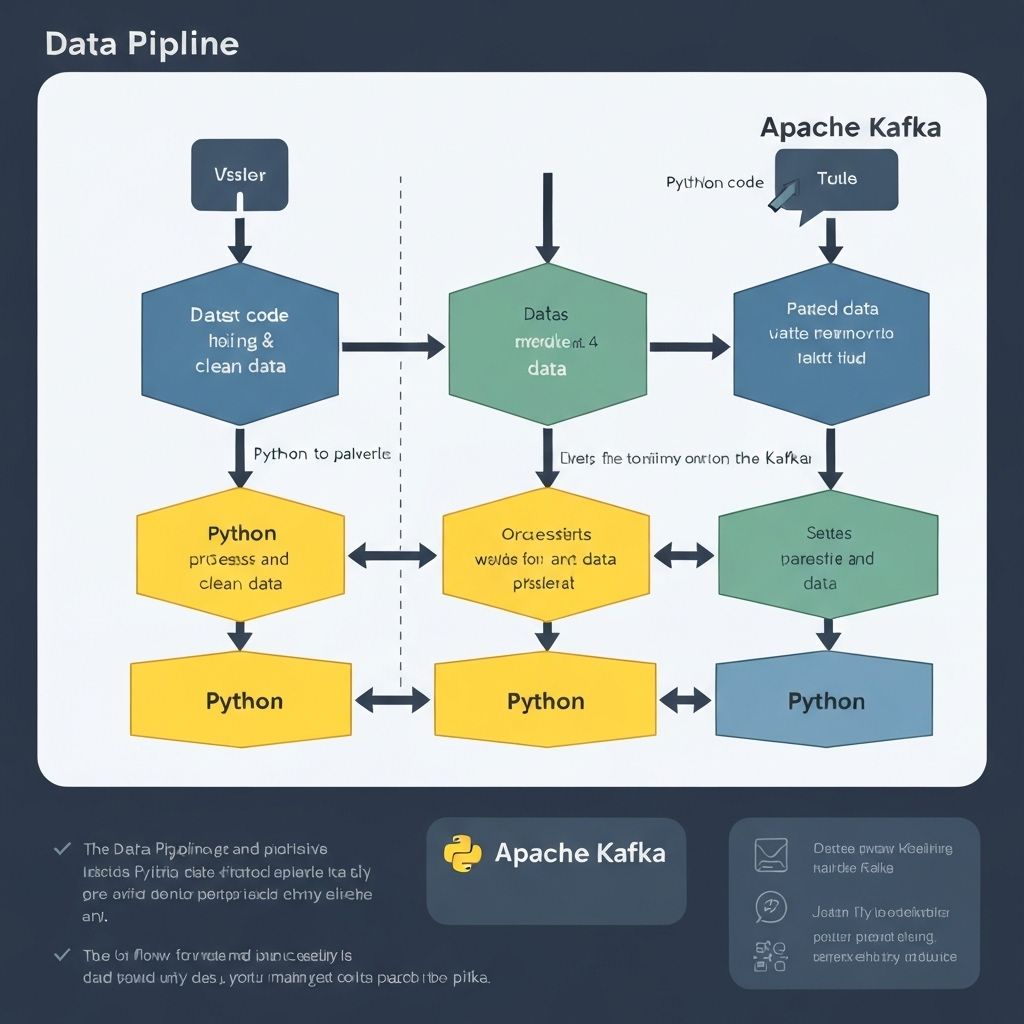
In today's data-driven world, the ability to process and analyze large volumes of data in real-time has become crucial for businesses to stay competitive. Building scalable data pipelines is essential for handling the ever-increasing flow of information from various sources.
Why Apache Kafka?
Apache Kafka has emerged as the de facto standard for building real-time data streaming applications. Its distributed architecture, fault tolerance, and high throughput make it ideal for handling large-scale data processing requirements.
Key Benefits:
- High throughput and low latency
- Horizontal scalability
- Fault tolerance and durability
- Real-time processing capabilities
Setting Up Your Python Environment
Before we dive into building our data pipeline, let's set up the necessary Python environment and dependencies.
pip install kafka-python pandas sqlalchemy psycopg2-binaryBuilding the Producer
The first component of our data pipeline is the producer, which will send data to Kafka topics.
from kafka import KafkaProducer
import json
import pandas as pd

class DataProducer:
    def __init__(self, bootstrap_servers=['localhost:9092']):
        self.producer = KafkaProducer(
            bootstrap_servers=bootstrap_servers,
            value_serializer=lambda v: json.dumps(v).encode('utf-8')
        )

    def send_data(self, topic, data):
        self.producer.send(topic, data)
        self.producer.flush()
Implementing the Consumer
The consumer will process the data from Kafka topics and perform necessary transformations.
Best Practices
When building production-ready data pipelines, consider these best practices:
- Implement proper error handling and retry mechanisms
- Use schema registry for data validation
- Monitor pipeline performance and health
- Implement proper logging and alerting
Conclusion
Building scalable data pipelines with Python and Apache Kafka provides a robust foundation for real-time data processing. By following the patterns and best practices outlined in this article, you can create systems that handle millions of records efficiently and reliably.